
AI News, Research and Tool Reviews
-
OpenAI o1 latency and cost realities
OpenAI o1 is approximately 30 times slower than GPT-4o and generates hidden reasoning tokens that increase total request costs. While o1 excels at complex math, it shows tendencies…
-
CoreWeave IPO pricing and Microsoft Azure GPU contract backlog
CoreWeave priced its IPO at $40 per share, raising $1.5 billion, while Microsoft accounted for 62 percent of its 2024 revenue. The…
-
How Google’s Willow Quantum Chip Is Changing AI Safety Research Timelines
Google’s Willow chip completed a benchmark in under five minutes, proving error rates drop exponentially as qubit counts increase.
-
Perplexity cuts enterprise search prices by 15% and lowers API minimums
Perplexity reduced annual Enterprise Pro seats to $34 and Enterprise Max to $271, a 15% drop, while cutting the minimum API credit…
-
SambaNova SN40L RDU vs NVIDIA H100: Enterprise Fine-Tuning Economics
NVIDIA H100s cost $25,000 to $30,000 each, while SambaNova SN40L pricing is undisclosed. The H100’s mature CUDA ecosystem reduces operational friction, making…
-
Positron FPGA inference architecture and Meta partnership lack public data
Public records contain no technical specifications or confirmation of a partnership between Positron and Meta regarding FPGA inference architecture. Available sources only…
-
Getting Started with Fireworks AI Inference
Fireworks AI provides ultra-low-latency inference for open-weight models, reducing operational costs by up to 40% compared to in-house GPU management.
-
Poolside’s $500M Funding and Autonomous Coding Risks
Poolside secured a $500 million Series B at a $3 billion valuation to build autonomous coding agents, yet its lack of a…
-
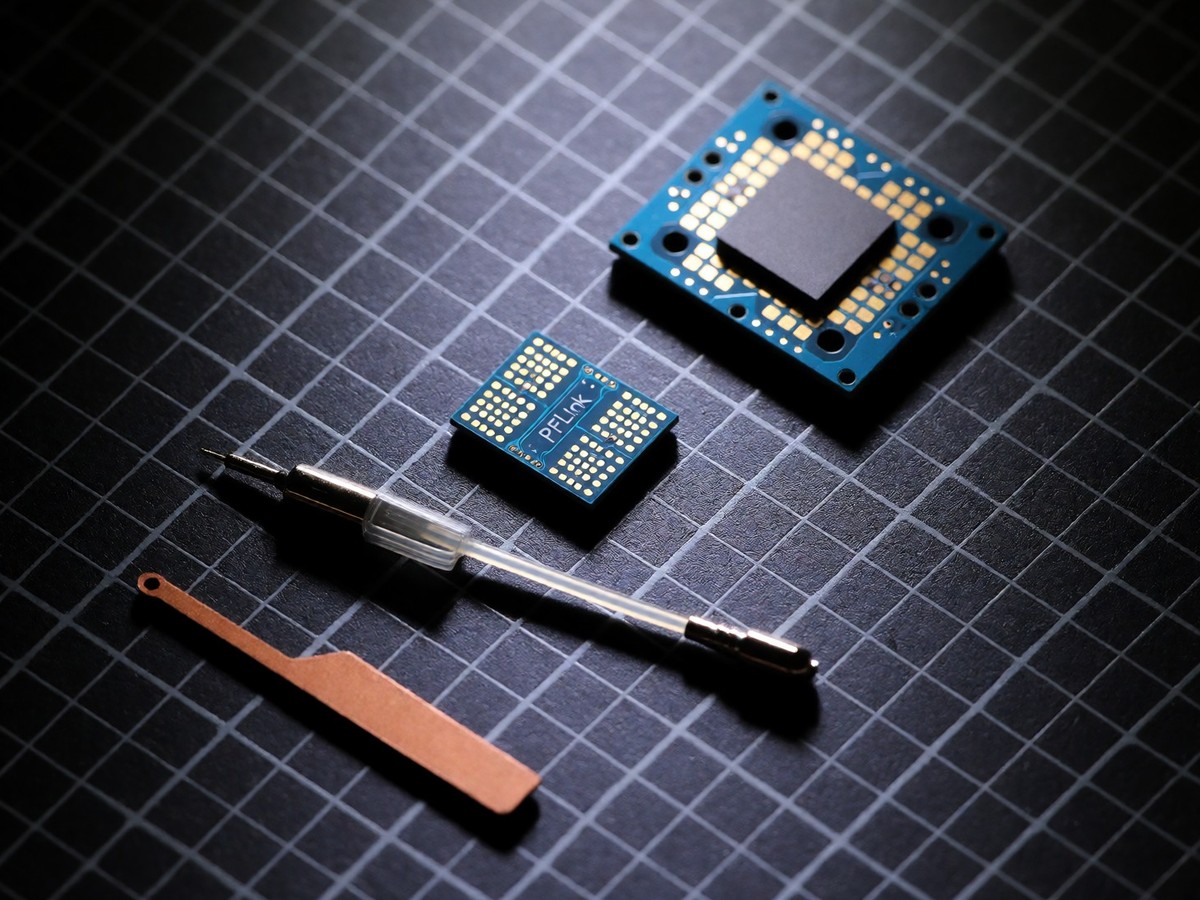
Why Celestial AI’s optical compute interconnect matters now for hyperscaler AI clusters
Marvell acquired Celestial AI for $3.25 billion to deploy Photonic Fabric, which delivers 14.4 to 16 Tbps per chiplet. This optical interconnect…